Guides · 8 min read
AI servers for local LLMs: Tesla P40, V100, L4 or A100?
How much GPU memory a language model needs, which data-centre GPU suits which budget and what matters for cooling, power and software.
Stock items leave our warehouse in Germany within 24 hours
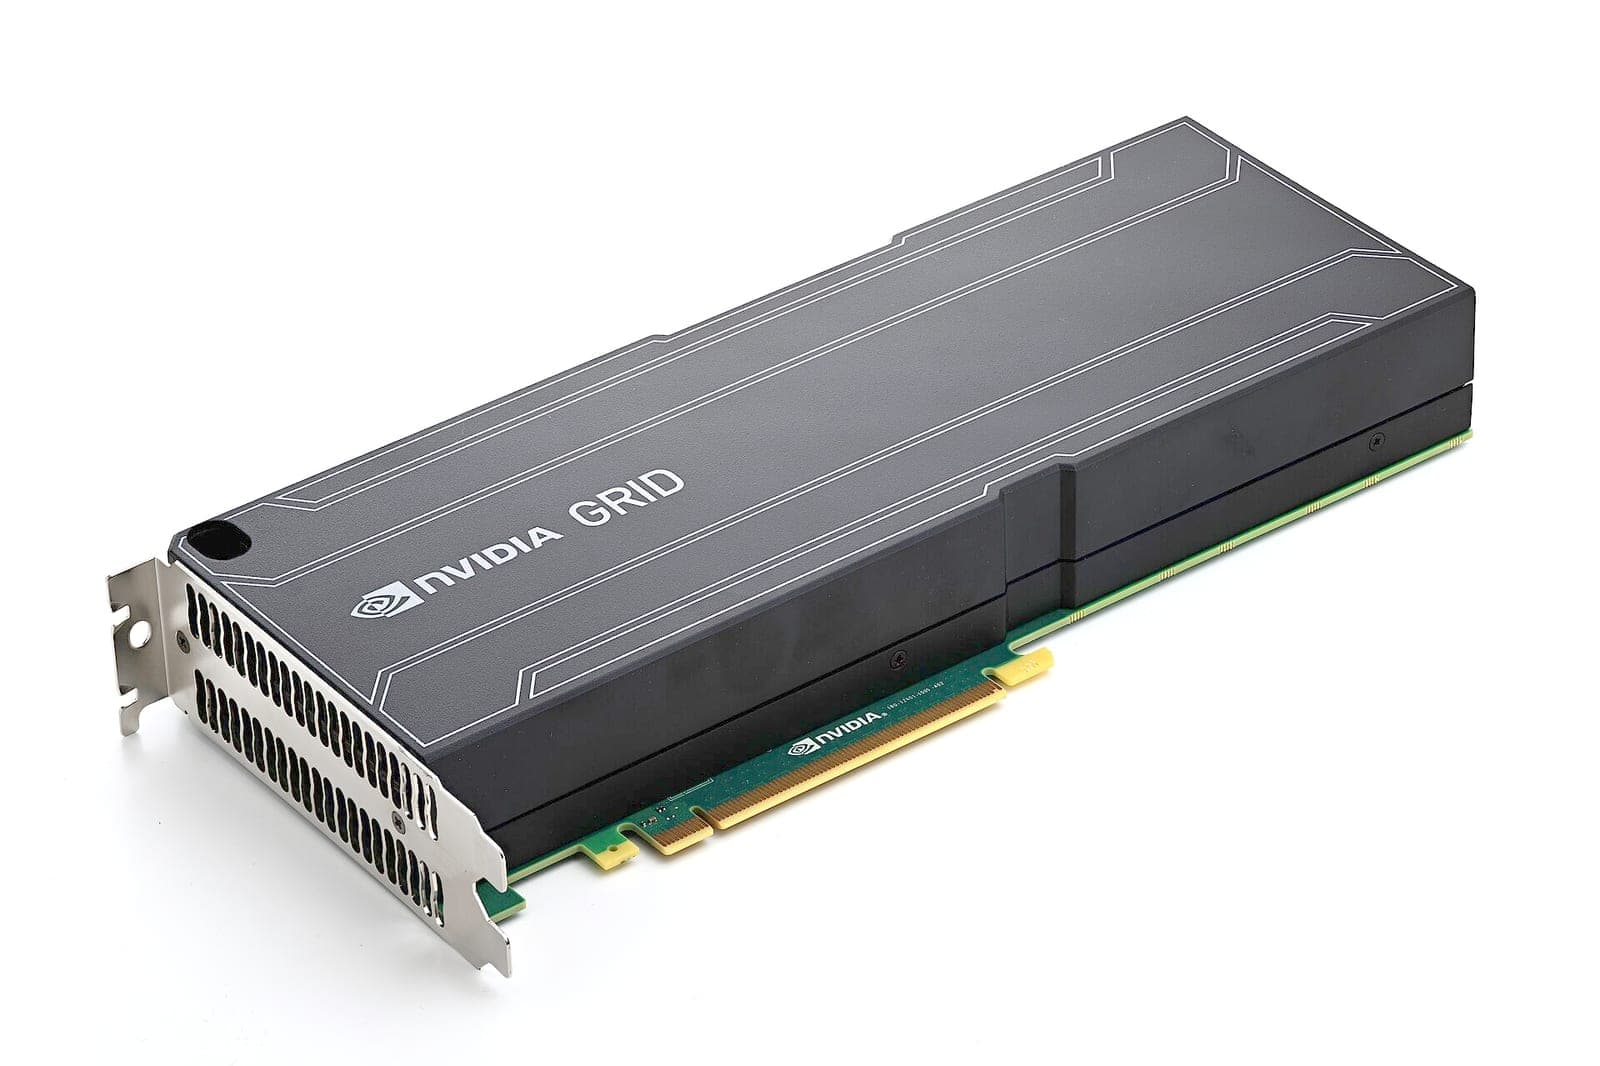
Server GPUs and AI accelerators from NVIDIA speed up inference and training of AI models, scientific computing, rendering, virtual desktops and video transcoding. The range goes from the affordable Tesla P40 with 24 GB through the low-power, low-profile T4 and L4 to the A100 with 80 GB HBM2e. Important before you buy: most data center cards are passively cooled and need the directed airflow of a server; workstations need additional cooling. Many models are powered through an 8-pin CPU (EPS-12V) connector rather than PCIe 8-pin, and dual-slot cards need a free full-height, full-length (FHFL) slot. Refurbished cards are cleaned, checked and tested. Warranty is 12 to 36 months.
No products found
Adjust the filters or ask us directly. We can source most hardware within a few days.
From the NVIDIA A100 with 80 GB of HBM2e to the Tesla P40 as an affordable 24 GB entry point: server GPUs differ less in raw compute than in memory size, bandwidth, form factor and power draw. The overview and the sections below show which card fits which server and what each one is good at.
| GPU | Generation | Memory | Bandwidth | TDP | Form factor |
|---|---|---|---|---|---|
| Tesla P40 | Pascal | 24 GB GDDR5 | 346 GB/s | 250 W | dual-slot FHFL, passive |
| Tesla T4 | Turing | 16 GB GDDR6 | 320 GB/s | 70 W | single-slot low profile, passive |
| Tesla V100 | Volta | 16 GB HBM2 | 900 GB/s | 250 W | dual-slot FHFL, passive |
| L4 | Ada Lovelace | 24 GB GDDR6 | 300 GB/s | 72 W | single-slot low profile, passive |
| A40 | Ampere | 48 GB GDDR6 with ECC | 696 GB/s | 300 W | dual-slot FHFL, passive |
| RTX A6000 | Ampere | 48 GB GDDR6 with ECC |
| 768 GB/s |
| 300 W |
| dual-slot FHFL, active |
| A100 40 GB | Ampere | 40 GB HBM2 | 1,555 GB/s | 250 W | dual-slot FHFL, passive |
|---|
| A100 80 GB | Ampere | 80 GB HBM2e | 1,935 GB/s | 300 W | dual-slot FHFL, passive |
|---|
The A100 comes into its own when memory size and bandwidth are the bottleneck: a language model generates tokens roughly as fast as the GPU can read its weights from memory, and the 80 GB version offers almost three times the bandwidth of an A40. For training it supports TF32 and BF16, and apart from the V100 it is the only card here that delivers fast double-precision (FP64) maths for simulation work.
Multi-Instance GPU (MIG) splits one A100 into up to seven isolated instances – 10 GB each on the 80 GB card. Two cards can be linked with an NVLink bridge. The A100 is built for PCIe 4.0; it runs in PCIe 3.0 servers, but loads data more slowly. Suitable systems are listed under GPU servers.
Pascal and Volta are supported by current CUDA 12 releases, but newer major CUDA versions require more recent generations. For long-running projects, Turing, Ampere and Ada are the safer bet.
The L4 succeeds the T4: the same low-profile format, but with 24 GB instead of 16, FP8 tensor cores and an AV1 encoder at just 72 W. It also runs in PCIe 3.0 servers, making it the easiest way to make an existing rack server AI-capable.
The RTX A6000 is actively cooled, so it is the only card in the list that works in a workstation without server airflow. Its passive server counterpart is the A40, also with 48 GB. The A40 is designed for vGPU as well, which requires a separate NVIDIA software licence; check the current terms directly with the vendor.
Our guide AI servers for local LLMs works out which card is enough for which language model. We buy retired cards through our buy-back service.
GPU memory is what counts. 24 GB (P40, L4) is enough for models up to about 30 billion parameters in 4-bit quantization, 48 GB (A40, RTX A6000) for 70B models. vLLM requires compute capability 7.0 or higher, so it runs from the V100 upwards but not on the P40; llama.cpp and Ollama also support the P40.
Only with additional cooling, such as a fan adapter that pushes air straight through the heatsink. Without directed airflow, passive cards throttle quickly or shut down. The actively cooled RTX A6000, on the other hand, is designed for workstations.
The Tesla P40, V100, A100, A40 and RTX A6000 use an 8-pin CPU (EPS-12V) connector. In servers, use the server vendor's GPU cable; in workstations, an adapter from two PCIe 8-pin plugs to one 8-pin EPS. The T4 and L4 are powered entirely through the PCIe slot.
Guides · 8 min read
How much GPU memory a language model needs, which data-centre GPU suits which budget and what matters for cooling, power and software.